Snowflake Result Cache Behavior and Its Limits
Understand when Snowflake's result cache works and when data changes invalidate it.
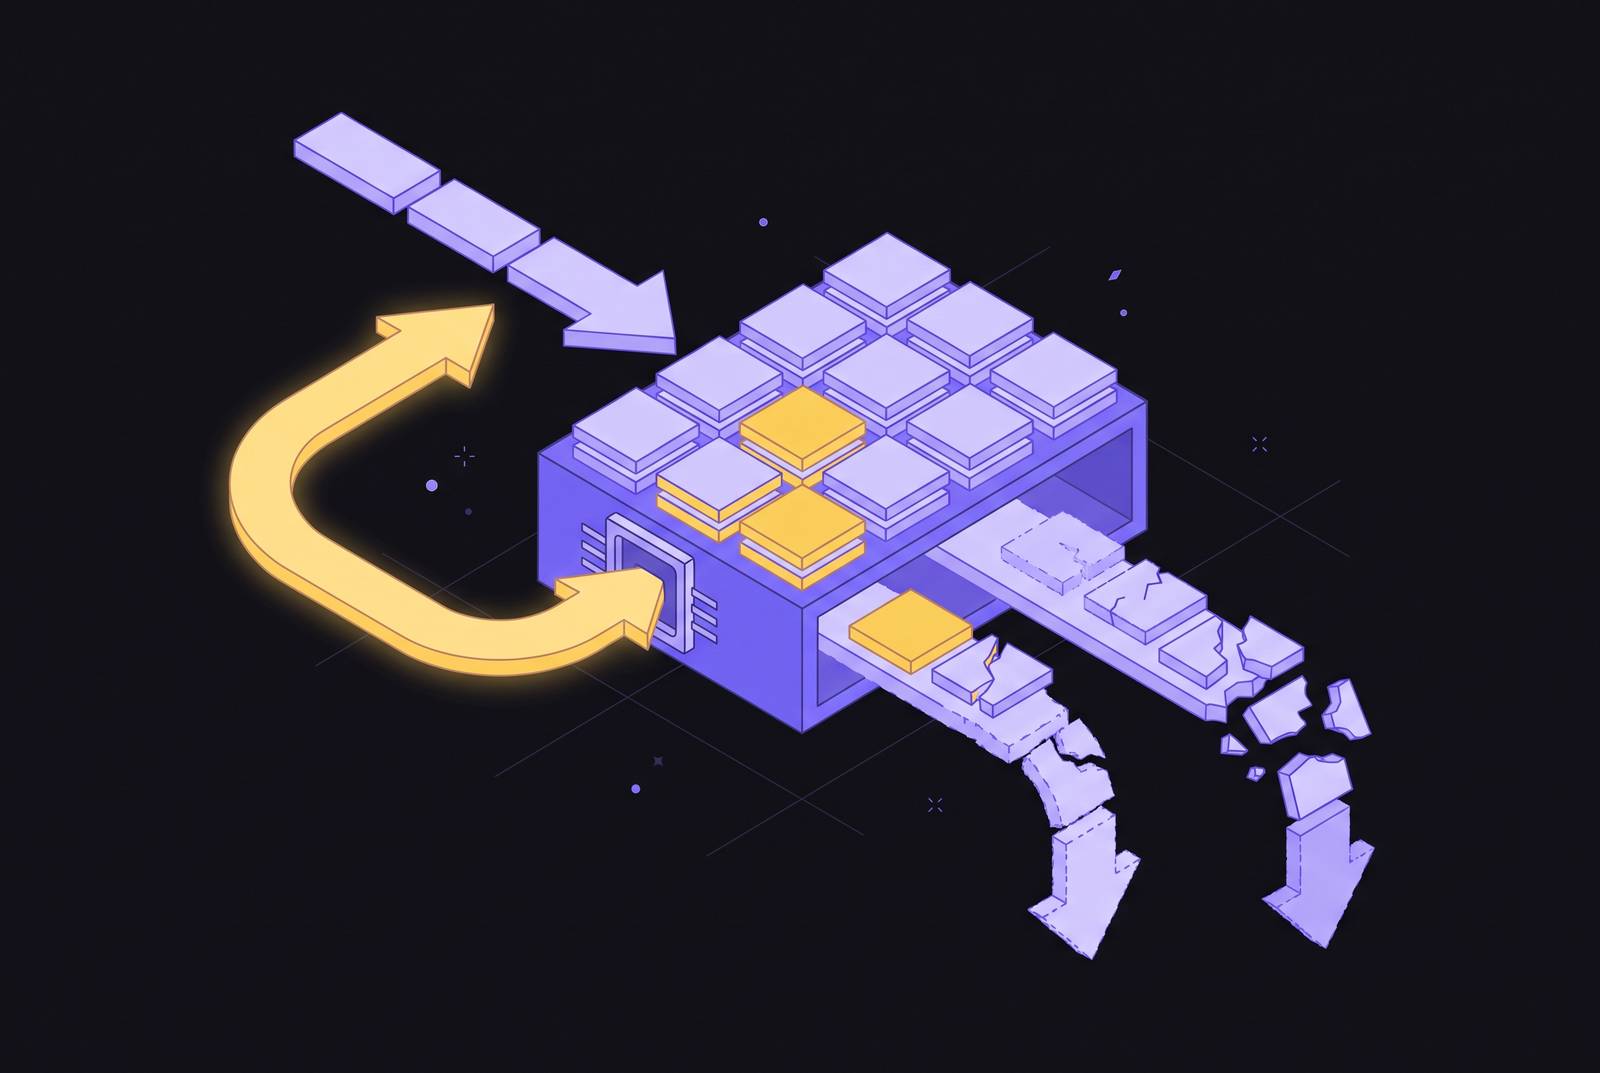
Its architecture separates three caches. Cloud Services holds persisted query results and metadata, while each warehouse holds a local SSD cache. A result cache hit needs no running warehouse and consumes no compute credits. Persisted results can be reused across warehouses, while warehouse-local data stays in its warehouse. This article focuses on that result cache and the limits that determine its value.
The exact conditions that must all be true for a result cache hit
Result reuse requires every eligibility condition to hold simultaneously as AND conditions. A single failure bypasses the cache without an error or warning. The first requirement is an exact query-text match with a previously executed query. Introducing a table alias or changing a keyword from uppercase to lowercase is enough to prevent reuse, even when the two statements ask for the same result.
The data contributing to that result must also remain unchanged. Physical changes can disqualify reuse without changing the query’s logical meaning. If micro-partitions have been reclustered or consolidated because of changes to other data in the table, the cached result is invalidated. Session or account-level configuration options that affect how the result was produced must remain unchanged too. Stable SQL alone is therefore not sufficient.
External functions and hybrid table reads prevent result-cache reuse, as do UUID_STRING, RANDOM, and RANDSTR. CURRENT_DATE() can be used in a query without ruling out reuse. That distinction separates an eligible time-based expression from a changing date literal embedded in the SQL text.
For SELECT, the executing role must have the required access privileges on every table used by the query. For SHOW, the role must exactly match the role that generated the cached result. The persisted result must also remain within its retention window, and cached-result reuse must not be disabled.
These rules are for persisted query results. Metadata can answer certain structural queries, including COUNT(*) and MIN/MAX on numeric, date, or timestamp columns, without a warehouse. MIN/MAX on string columns instead requires a scan. Consequently, warehouse-free execution is not a reason to treat metadata and result caching as interchangeable. The result cache reuses a prior result, while the metadata cache serves the structural queries described above.
How the 24-hour window and the 31-day ceiling interact
A persisted result is initially available for 24 hours. Each reuse resets that window, allowing an eligible result to remain available beyond the day when it was first generated. The reset is not an indefinite extension, however. Snowflake imposes an absolute limit of 31 days from the date and time of the original execution. At that point, the result is purged regardless of its most recent reuse, and the next submission generates a fresh result.
The two clocks answer different operational questions. A query repeated within each rolling window can benefit from reuse across multiple days, provided all other conditions continue to hold. A query left unused for more than 24 hours cannot rely on the longer limit to preserve its result.
Large results introduce a separate retrieval constraint. For result sets over 100 KB, the access token expires after 6 hours. That token lifetime is shorter than the cache retention window. A pipeline that retrieves results hours after they were generated may therefore need a new token while the persisted result is still cached. A new token can be retrieved while the result is still cached, so token expiry and result expiry require different diagnoses.
None of these timers overrides the data-change rules. A change to the underlying table can invalidate a result before its rolling window expires. Frequent reuse cannot protect it from reclustering or other disqualifying changes either. Cache longevity therefore depends on both time and stability. Either dimension can independently rule out reuse.
Why the result cache rarely fires in dynamic, per-user SaaS query patterns
A shared finance report is well suited to exact-text reuse. Its users can run the same SQL against data that stays the same between updates. A personalized analytics dashboard has a different structure. Each user’s filters can give the query a different WHERE clause, so queries with the same structure can have different query text. The cache cannot substitute one user’s filtered result for another’s.
A pattern such as WHERE tenant_id =? can produce many distinct queries as different tenant values enter the submitted SQL. Those queries cannot reuse each other’s cached results merely because they share a template. An individual tenant may still repeat an identical query. The limitation is that repetition must occur within that exact query’s eligibility and retention boundaries, rather than across the product’s broader volume of similar requests.
Continuous ingestion narrows the opportunity further. A single INSERT into a referenced table can invalidate a cached result before an identical request returns. High request volume therefore does not necessarily produce high reuse. Automatic clustering adds another invalidation path when its runs change micro-partitions, independent of changes to the contributing data. A busy dashboard over a table that is often maintained may keep losing eligibility as both the query text and the table state change.
The warehouse cache can help repeated scans within a session, but it remains private to its warehouse and requires an active warehouse. Its contents are lost when the warehouse suspends, resizes, or a node is replaced. That makes it unlike a global store of completed responses available across warehouse boundaries. Treating it as a substitute for result reuse obscures the distinction between accelerating execution and avoiding execution.
Shared executive dashboards and scheduled reports often supply the literal repetition that the result cache requires. User-facing interfaces with changing filters often do not. Evaluate how often the same eligible request returns before its data, physical layout, configuration, or retention status changes.
Design patterns that reliably produce cache hits versus those that guarantee misses
Keep query text fixed where the product allows it. Scheduled BI reports work well when their data stays the same between runs. Shared aggregates can also work well on tables that change slowly. Stable repetition enables a COUNT(*) or SUM() query against a table updated only nightly to retain a reusable result during the day for eligible users submitting identical SQL.
SHOW commands offer another useful reuse pattern. Their results can be post-processed with RESULT_SCAN, allowing the follow-up query to vary without re-executing the underlying SHOW. The original SHOW still has its role-match requirement. Where repeated dashboard reads are genuinely served by the result cache, a short auto-suspend interval is also reasonable. Losing warehouse-local cached data is less consequential when those reads do not need warehouse execution.
Avoid treating SQL that changes as a reusable request: WHERE date = CURRENT_DATE and WHERE date = '2026-10-21' have different query text. CURRENT_DATE() itself is not the disqualifier. When a resolved date string changes between submissions, the exact-text requirement fails. The same principle applies to other dynamic values embedded directly into the SQL string.
Some query features rule out reuse more directly. UUID_STRING, RANDOM, RANDSTR, external functions, and hybrid table reads belong in that group. Frequently changing micro-partitions also prevent a result from remaining reusable across clustering runs. Role changes require more precise treatment than a blanket prohibition. They block reuse for SHOW, while SELECT depends on the required privileges and, where relevant, role-dependent masking.
When per-user filters cannot be stabilized, use complementary strategies. The available approaches include materialized views on common aggregates, pre-computed summary tables written to a stable schema, and structured exports to destinations where application-layer caching can operate. These address reuse at a layer better matched to the workload. For performance testing, disable USE_CACHED_RESULT at session level to measure execution without persisted results skewing the benchmark. That separates the cost of running a query from the benefit of avoiding it.
How role-scoping and data masking interact with the cache in multi-tenant environments
A role without the required table privileges cannot get a cached SELECT result just because another role created it. The privilege check applies even with identical SQL and unchanged data, preventing privilege escalation through cached results. The performance opportunity must therefore be evaluated within the access model.
Dynamic data masking also makes reuse depend on the policy. A result cached for one role’s masked view cannot automatically be used for another role’s different masked view. Roles with different masking policies each get their own cache entries. In a multi-tenant product with different customer roles and role-dependent views, this splits reuse among requests that are otherwise alike. Each such entry has its own 24-hour clock, rather than sharing one pooled history of eligible repetition.
More role-specific entries narrow reuse and reduce the savings a team might have expected from treating logically similar queries as one shared workload. However, role identity alone should not be confused with the privilege rule for SELECT. The relevant distinction is whether the request satisfies the required access and policy conditions. SHOW retains the stricter requirement of an exact role match.
Advanced security features such as customer-managed encryption keys and private connectivity are available only in higher-cost editions, including Business Critical or VPS. Organizations that need those features must weigh the cost of the edition along with the savings they expect from the cache. For SaaS vendors exposing query results to customers, a white-label data integration layer that handles consistent role management, SOC 2-compliant data handling, and end-to-end encryption is infrastructure. Its role model needs to be designed from the start so that repeatable delivery does not conflict with access boundaries.
What to verify when the result cache is not firing as expected
First, check whether the query used warehouse execution. If the profile shows a warehouse executing the query, the result cache was bypassed. Compare the submitted text with the earlier statement character-for-character, including whitespace, aliases, and keyword case. This first check separates a text mismatch from problems that require examining table state or permissions.
Next, inspect changes since the earlier execution. Check for DML on referenced tables, then for micro-partition changes caused by clustering or consolidation. These are distinct invalidation paths. The values a table contributes to a result can look unchanged even when its physical layout has changed. Also check whether session or account configuration affecting the result differs from the earlier execution.
Then examine the executing role and query features. For SELECT, verify the required privileges and any role-dependent masking context. For SHOW, verify that the role matches exactly. Check for UUID_STRING, RANDOM, RANDSTR, external functions, and hybrid table reads. Finally, check whether USE_CACHED_RESULT has been set to FALSE at the session, user, or account level.
Retention and retrieval require their own checks. Check for more than 24 hours without reuse or a result that has reached the 31-day absolute limit. For results over 100 KB, also check the 6-hour access-token window. A result can still be cached after its token has expired. Retrieve a new token where the result is still available, rather than treating both failures as the same cache problem.
For workload-wide diagnosis, INFORMATION_SCHEMA’s QUERY_HISTORY can distinguish cache-served queries from executed queries and support a cache-hit-rate audit. Use USE_CACHED_RESULT = FALSE to measure baseline execution time on purpose. Production bypasses should not substitute for controlled performance testing. If the audit repeatedly points to unavoidable dynamic query patterns, move reuse to a controllable layer through pre-computed exports, stable summary tables, or consistent data delivery to downstream destinations. The architectural response is to build around repeatability the product can provide, rather than depend on ad-hoc requests becoming identical by chance.